

Common Ground - speak once, meet the room.
Common Ground is a real-time communication-adaptation engine for meetings, demos, onboarding, and presentations. It transcribes live speech (or reprocesses uploads), keeps the verbatim source visible, rewrites the same explanation for five distinct audience types, and produces a structured recap of decisions, action items, risks, and follow-ups - with a deterministic demo mode that runs with no API keys at all.

One explanation almost never lands the same way for an executive, a client, an engineer, and a new hire in the same room. Presenters re-explain on the fly, lose the thread, and leave the meeting without a clean record of what was actually decided.
Common Ground treats a single message as adaptable material: it keeps the original words intact, rewrites the framing per audience in real time, and distills the conversation into a decision-grade recap - so the same words meet every person where they are, and nothing gets lost after the call.
One message, adapted for every room.
Captures speech as it happens
Common Ground taps the browser's Web Speech API for live transcription, with a graceful non-blocking fallback when recognition is unavailable - and an upload path that reprocesses recorded audio through the same pipeline. The original transcript is never discarded; it stays visible next to every rewrite.
Rewrites one message for five rooms
The same source is re-framed on demand for Executive, Client, Engineer, New-hire, and Non-native-speaker audiences. Each mode is a distinct rhetorical target - altitude, jargon density, and sentence complexity all shift - while the underlying facts stay locked to the source so nothing is invented in translation.
Extracts a decision-grade recap
A structured extraction layer parses free-form conversation into Summary, Decision, Action, and Risk fields - and reports honestly when a field has no signal ("No decision detected yet") instead of hallucinating one. The recap is exportable the moment the meeting ends.
Runs fully offline for demos
Demo mode is deterministic and provider-agnostic: three preloaded scenarios and every audience mode run with zero external AI calls, so a live demo can never fail on a flaky network or a missing key. Live mode layers real speech recognition on top when the environment supports it.
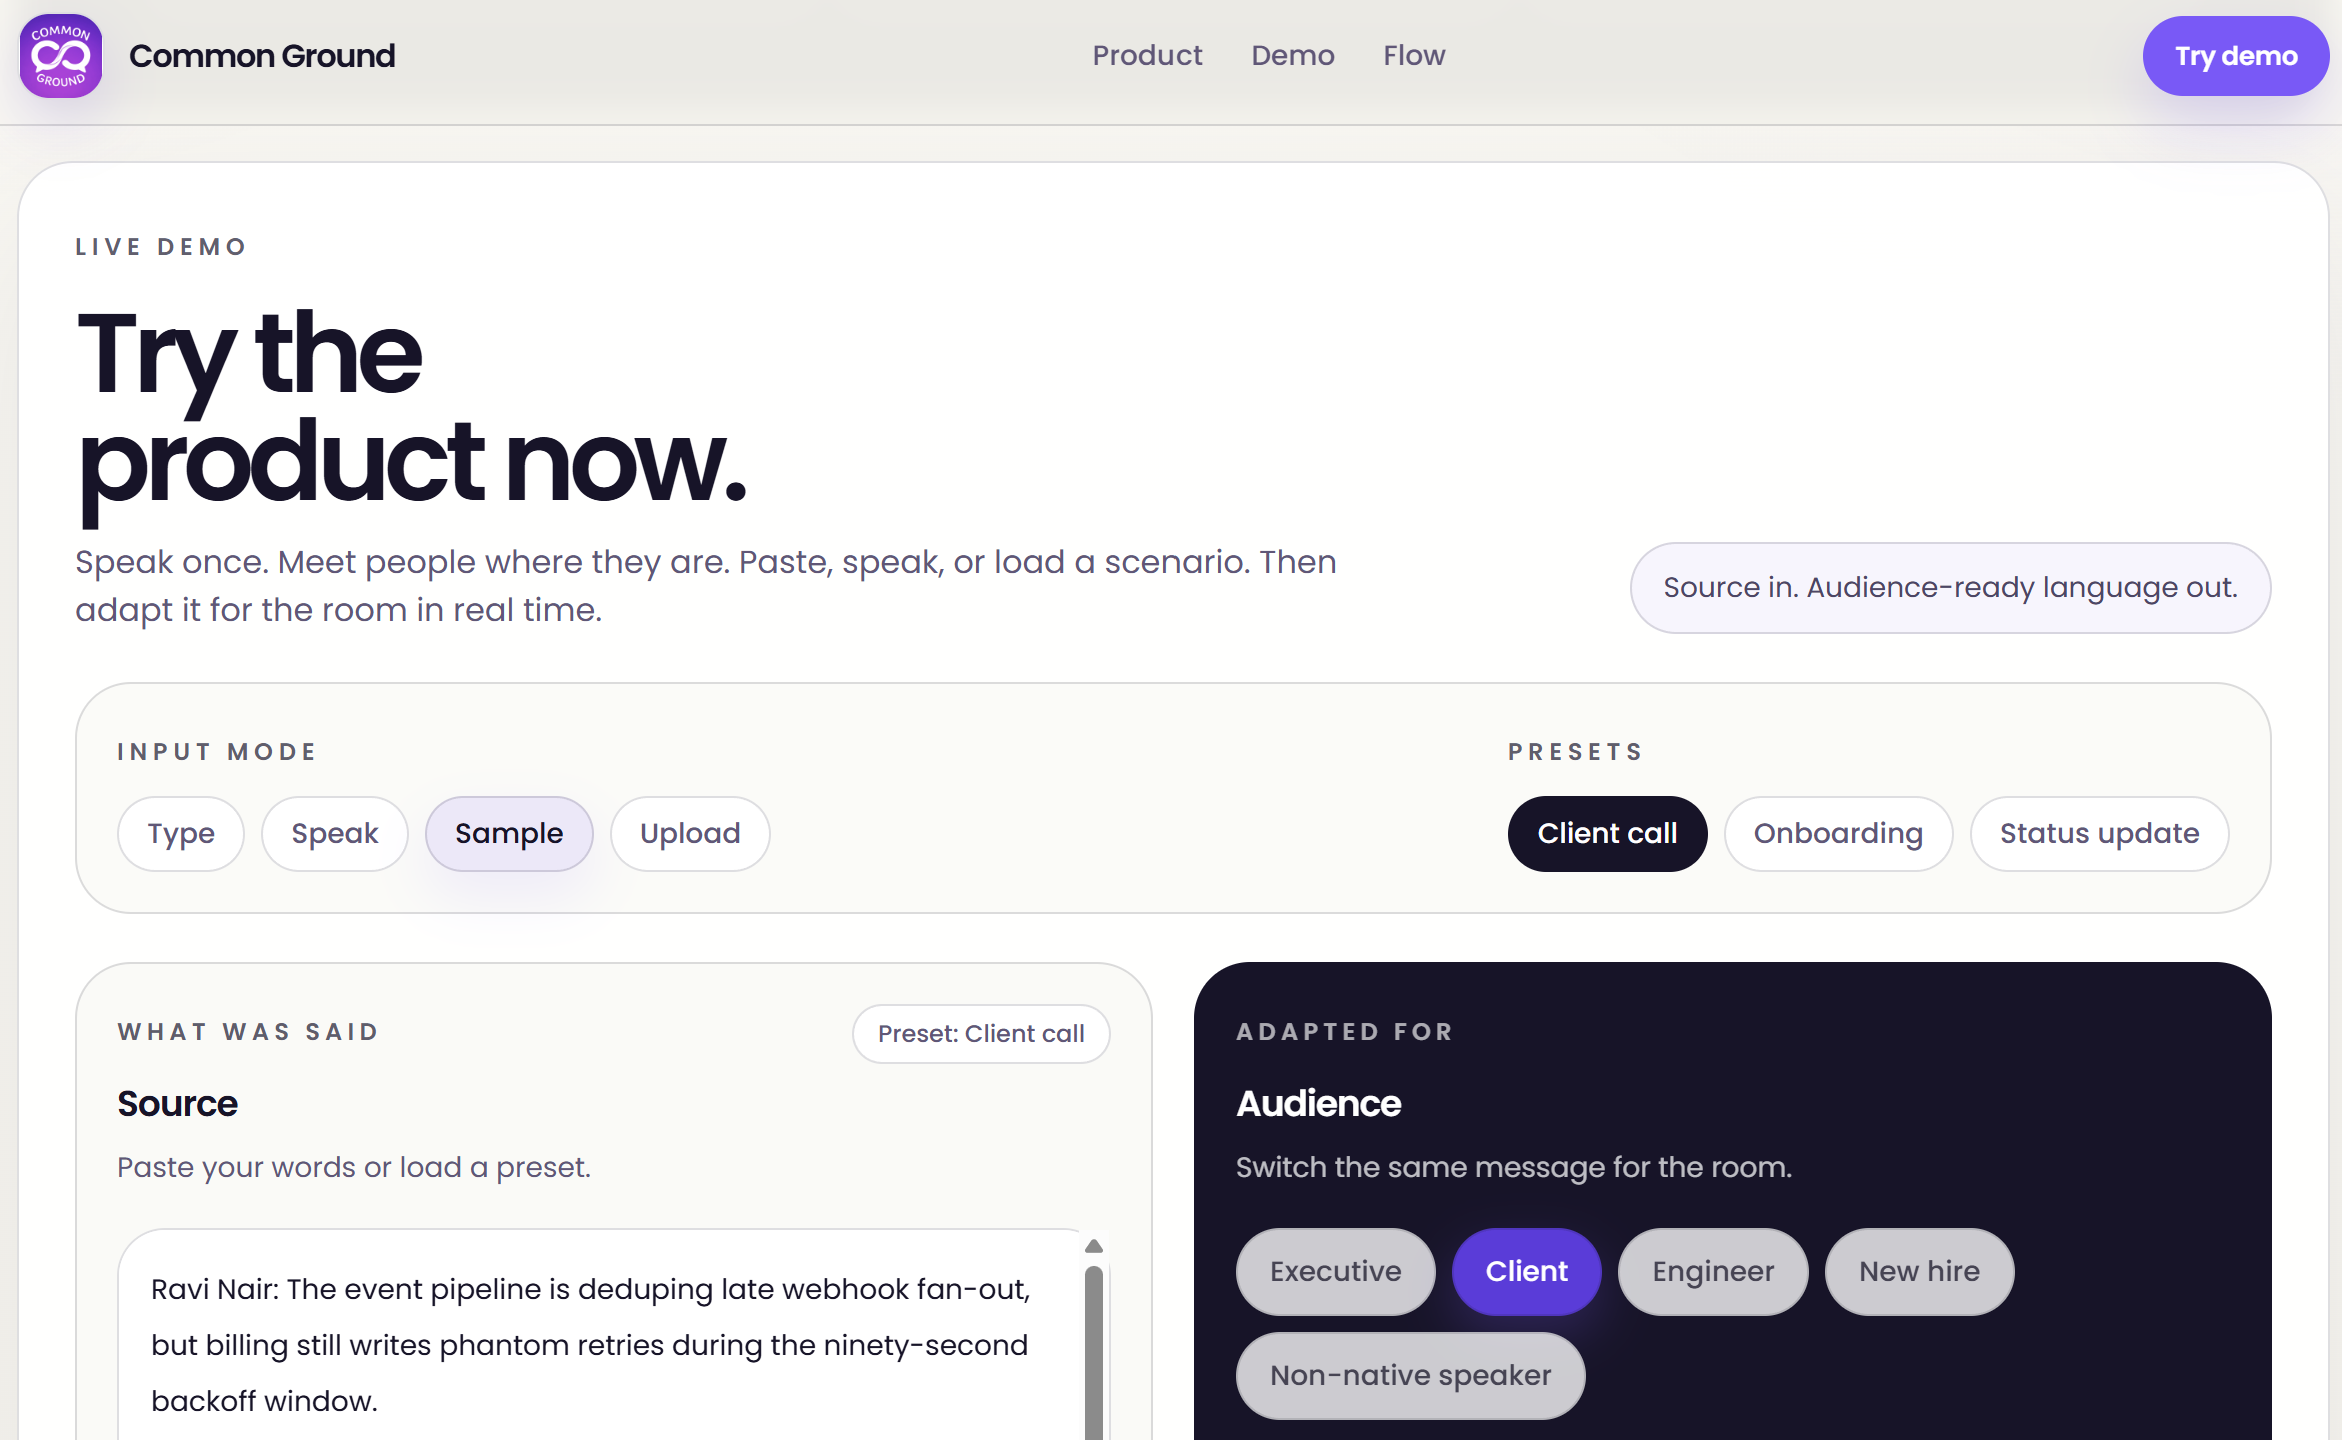
Source in. Audience-ready language out.
The hard part is not paraphrasing - it is re-framing the same facts across five audiences without drifting from what was actually said. Common Ground pins every rewrite to the verbatim source, so an engineer's version and an executive's version disagree on altitude and jargon but never on substance. Switching audience is a single click, and the source stays visible the whole time.
Capture, adapt, recap.
The whole flow is built to survive a live room: speech is captured as it happens, the source is preserved, the framing adapts on demand, and a structured recap is assembled in real time - deterministically enough to demo with the network unplugged.
- 01Capture speech live, or ingest an uploaded recording
- 02Preserve the verbatim source transcript, always visible
- 03Adapt the message per audience persona in one click
- 04Extract summary, decision, action, and risk in real time
- 05Export a shareable recap and persist the session locally
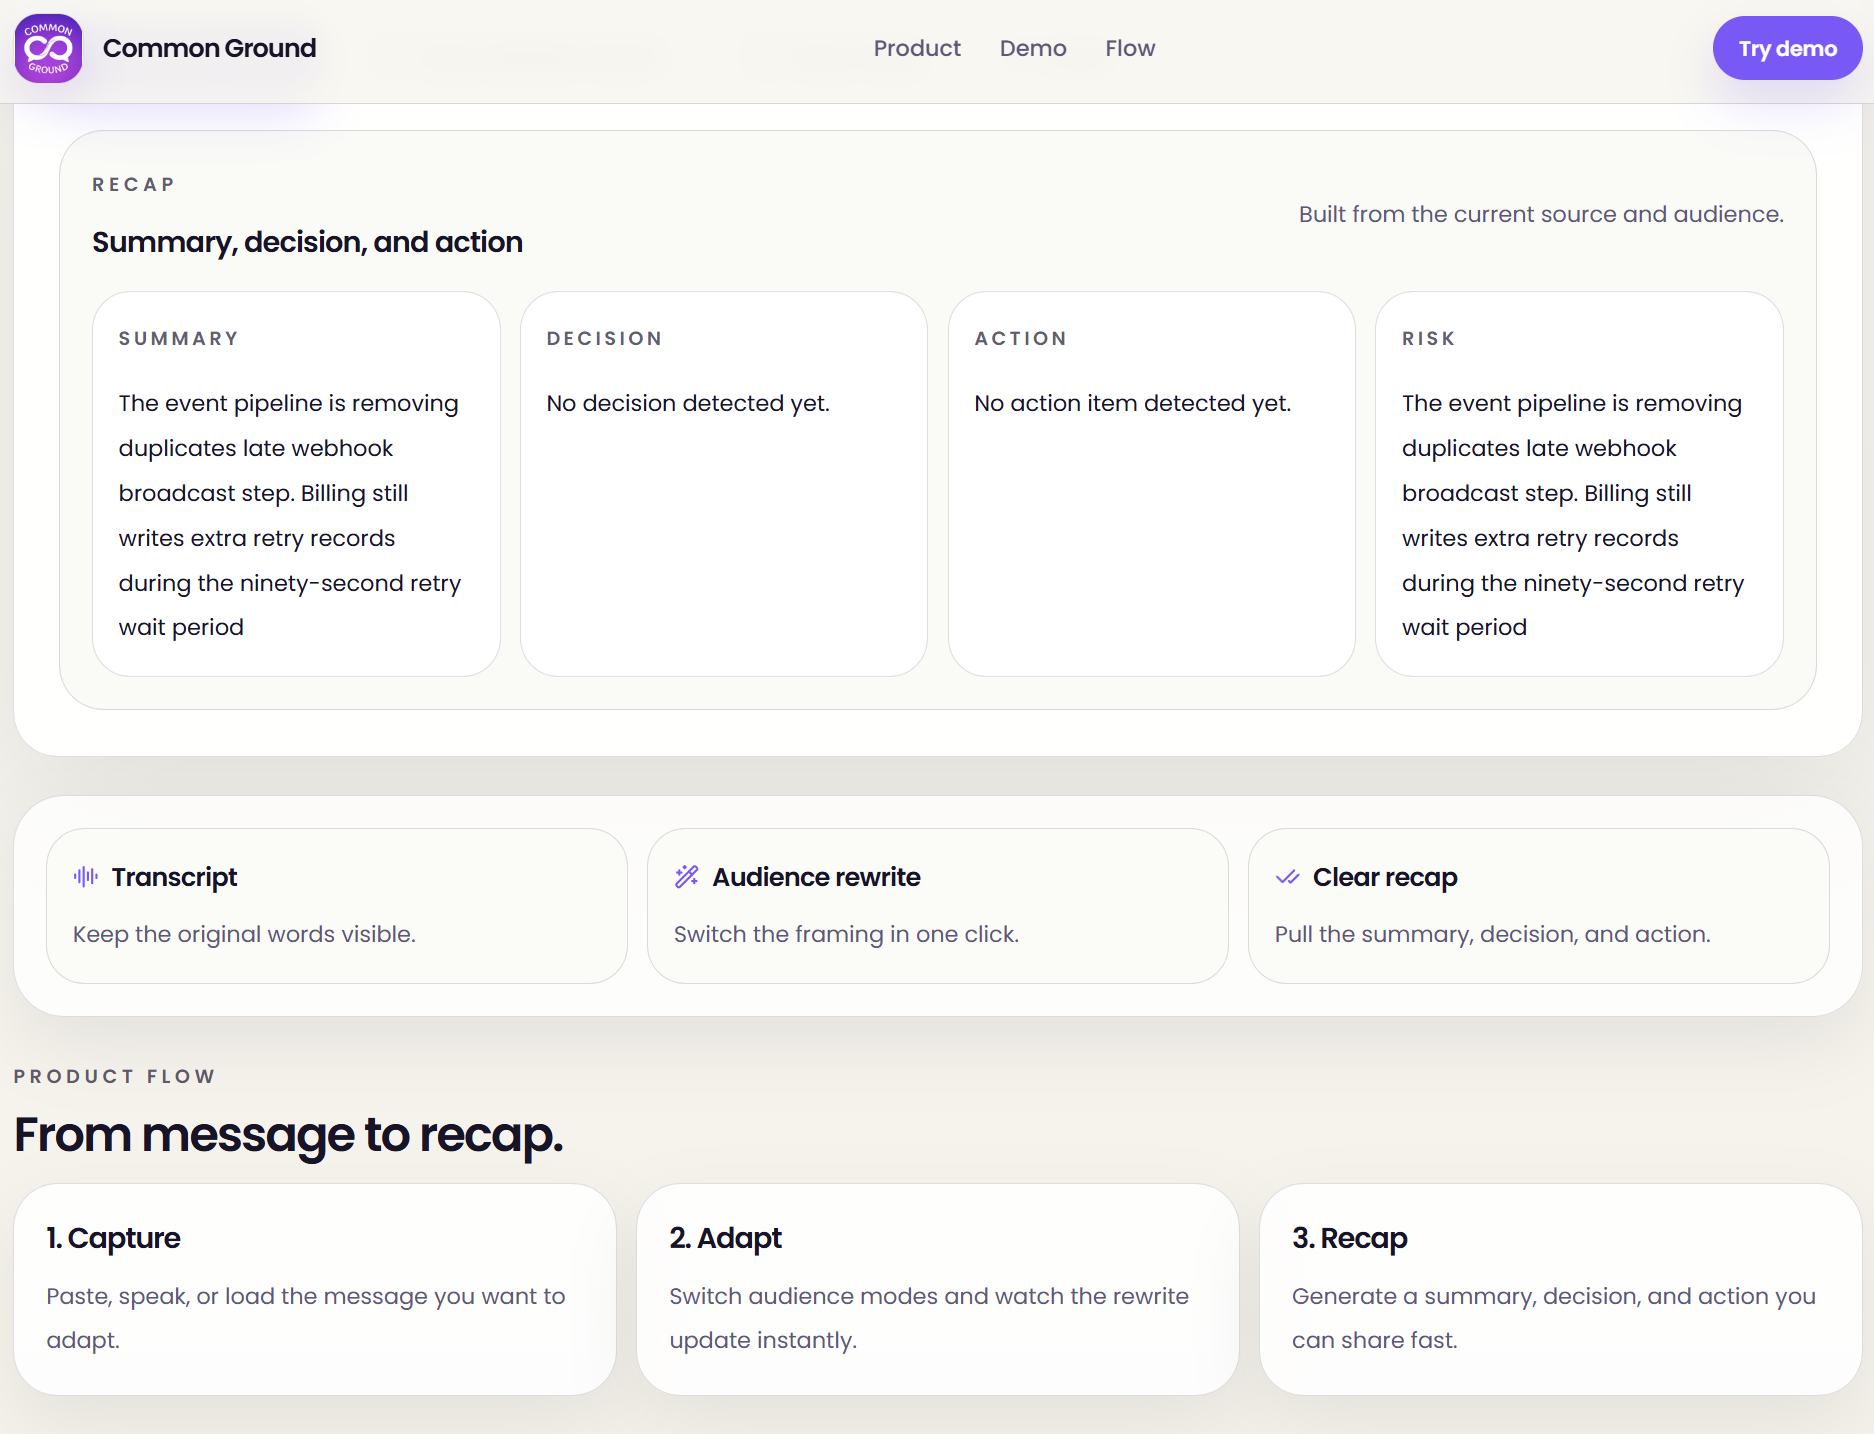
Three layers, one transcript.
Capture layer
Browser speech recognition with capability detection and a graceful fallback, plus an upload-and-reprocess path - all feeding one normalized transcript model.
Adaptation layer
A per-audience rewrite pipeline that re-frames the same source without mutating its facts, driven by a provider abstraction that swaps between deterministic demo output and live AI.
Recap layer
Structured extraction into decision-grade fields with explicit no-signal handling, exportable output, and local session persistence for the history and detail views.
The work behind Common Ground
Real-time communication adaptation: speech or recordings come in, the original transcript stays visible, and the same explanation is rewritten per audience alongside a structured recap of decisions and actions.
Services this build draws on
- Artificial IntelligenceFrom machine learning and natural language to computer vision and predictive analytics, we build a full suite of AI capabilities - tailored to how your business actually works, with a person reviewing the decisions that matter. No black boxes, no hype.Read the service page
- AI Workflow AutomationWe design AI-assisted workflows that remove the manual, repetitive steps slowing your team down - with a human in the loop wherever judgement matters. Built around how your business already works, not a template.Read the service page
